OMICS-based drug discovery
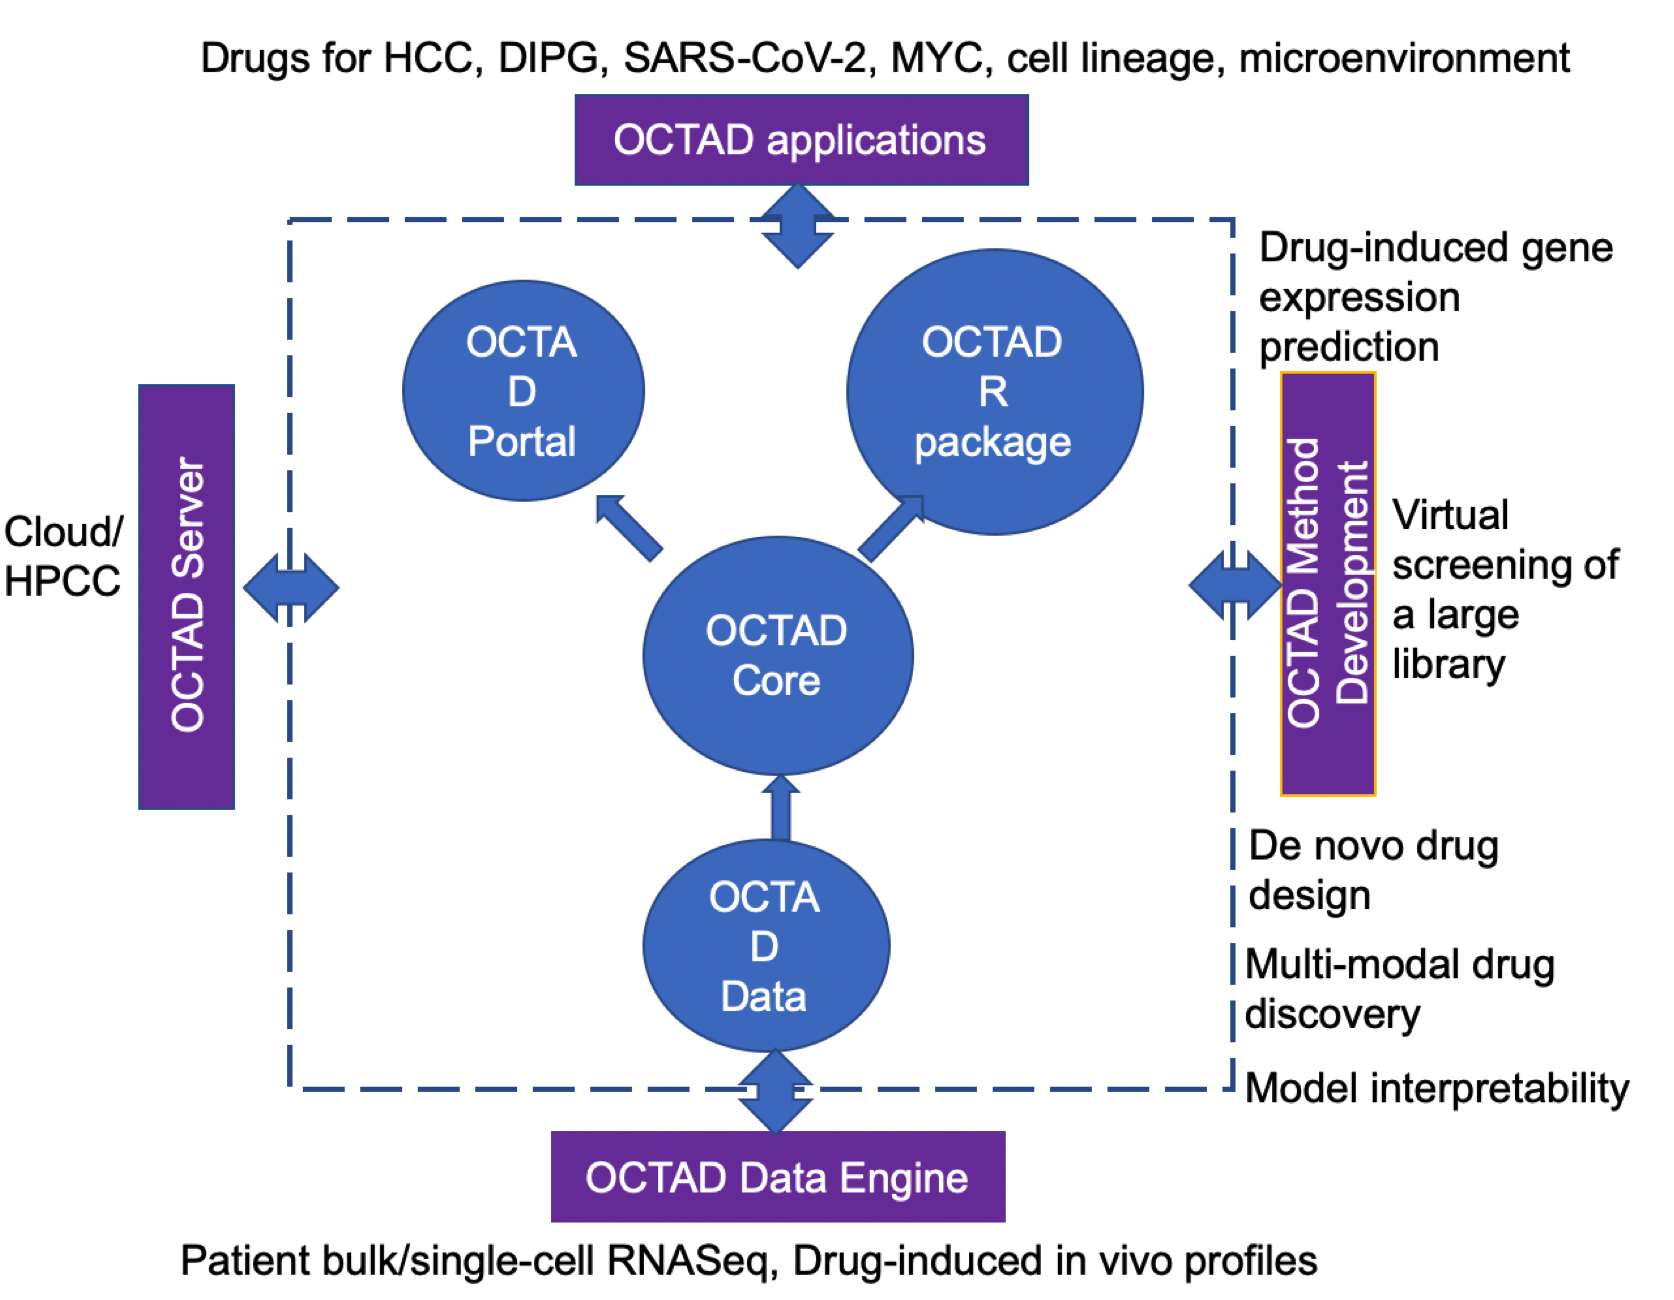
Conventional drug discovery focuses on finding agents that modulate a single molecular feature, usually a protein target. This approach was adopted decades ago, before the emergence of omics technologies. Today's technologies can profile thousands of molecular features, including proteins, mRNAs, and metabolites, all of which can contribute to disease development. Finding one magic bullet among these thousands of features is challenging. Moreover, focusing on a single feature does not make full use of the information generated by new omics technologies. We employ a systems approach that considers how drugs affect a disease gene expression signature (a set of up- and down-regulated disease genes). This approach has led to the discovery of therapeutic candidates for hepatocellular carcinoma (HCC), Ewing sarcoma, basal cell carcinoma, melanoma, Alzheimer's disease, diffuse intrinsic pontine glioma (DIPG), prostate cancer bone metastasis, and SARS-CoV-2. We also found that a drug's potency in reversing disease gene expression correlates with its efficacy, providing strong evidence for using this approach in drug repurposing (Chen, Nature Communications, 2017). We developed a drug repurposing platform called OCTAD (Zeng, Nature Protocols, 2021), which allows researchers to predict repurposed drug candidates for cancers and cancer subtypes.
We actively develop new methods to support novel compound screening and lead optimization. Our recent conference papers have demonstrated their feasibility by improving training data quality (Sun, ICDM, 2020), pre-training graph neural networks (Sun, KDD, 2021), and applying tree search-based multi-objective optimization (Sun, KDD, 2022). Our models can now quickly predict novel compounds from disease gene expression profiles. The lab has set up a bench to validate new candidates for multiple diseases, including HCC, DIPG, and SARS-CoV-2.
With the emergence of single-cell RNA-seq data, we apply this approach to identify compounds that could control cell lineage development or modulate the microenvironment. This approach also holds great promise for identifying novel inhibitors of undruggable targets. On the technical side, we develop methods that support de novo drug design using advanced machine learning.
OMICS-based biomarker and target identification
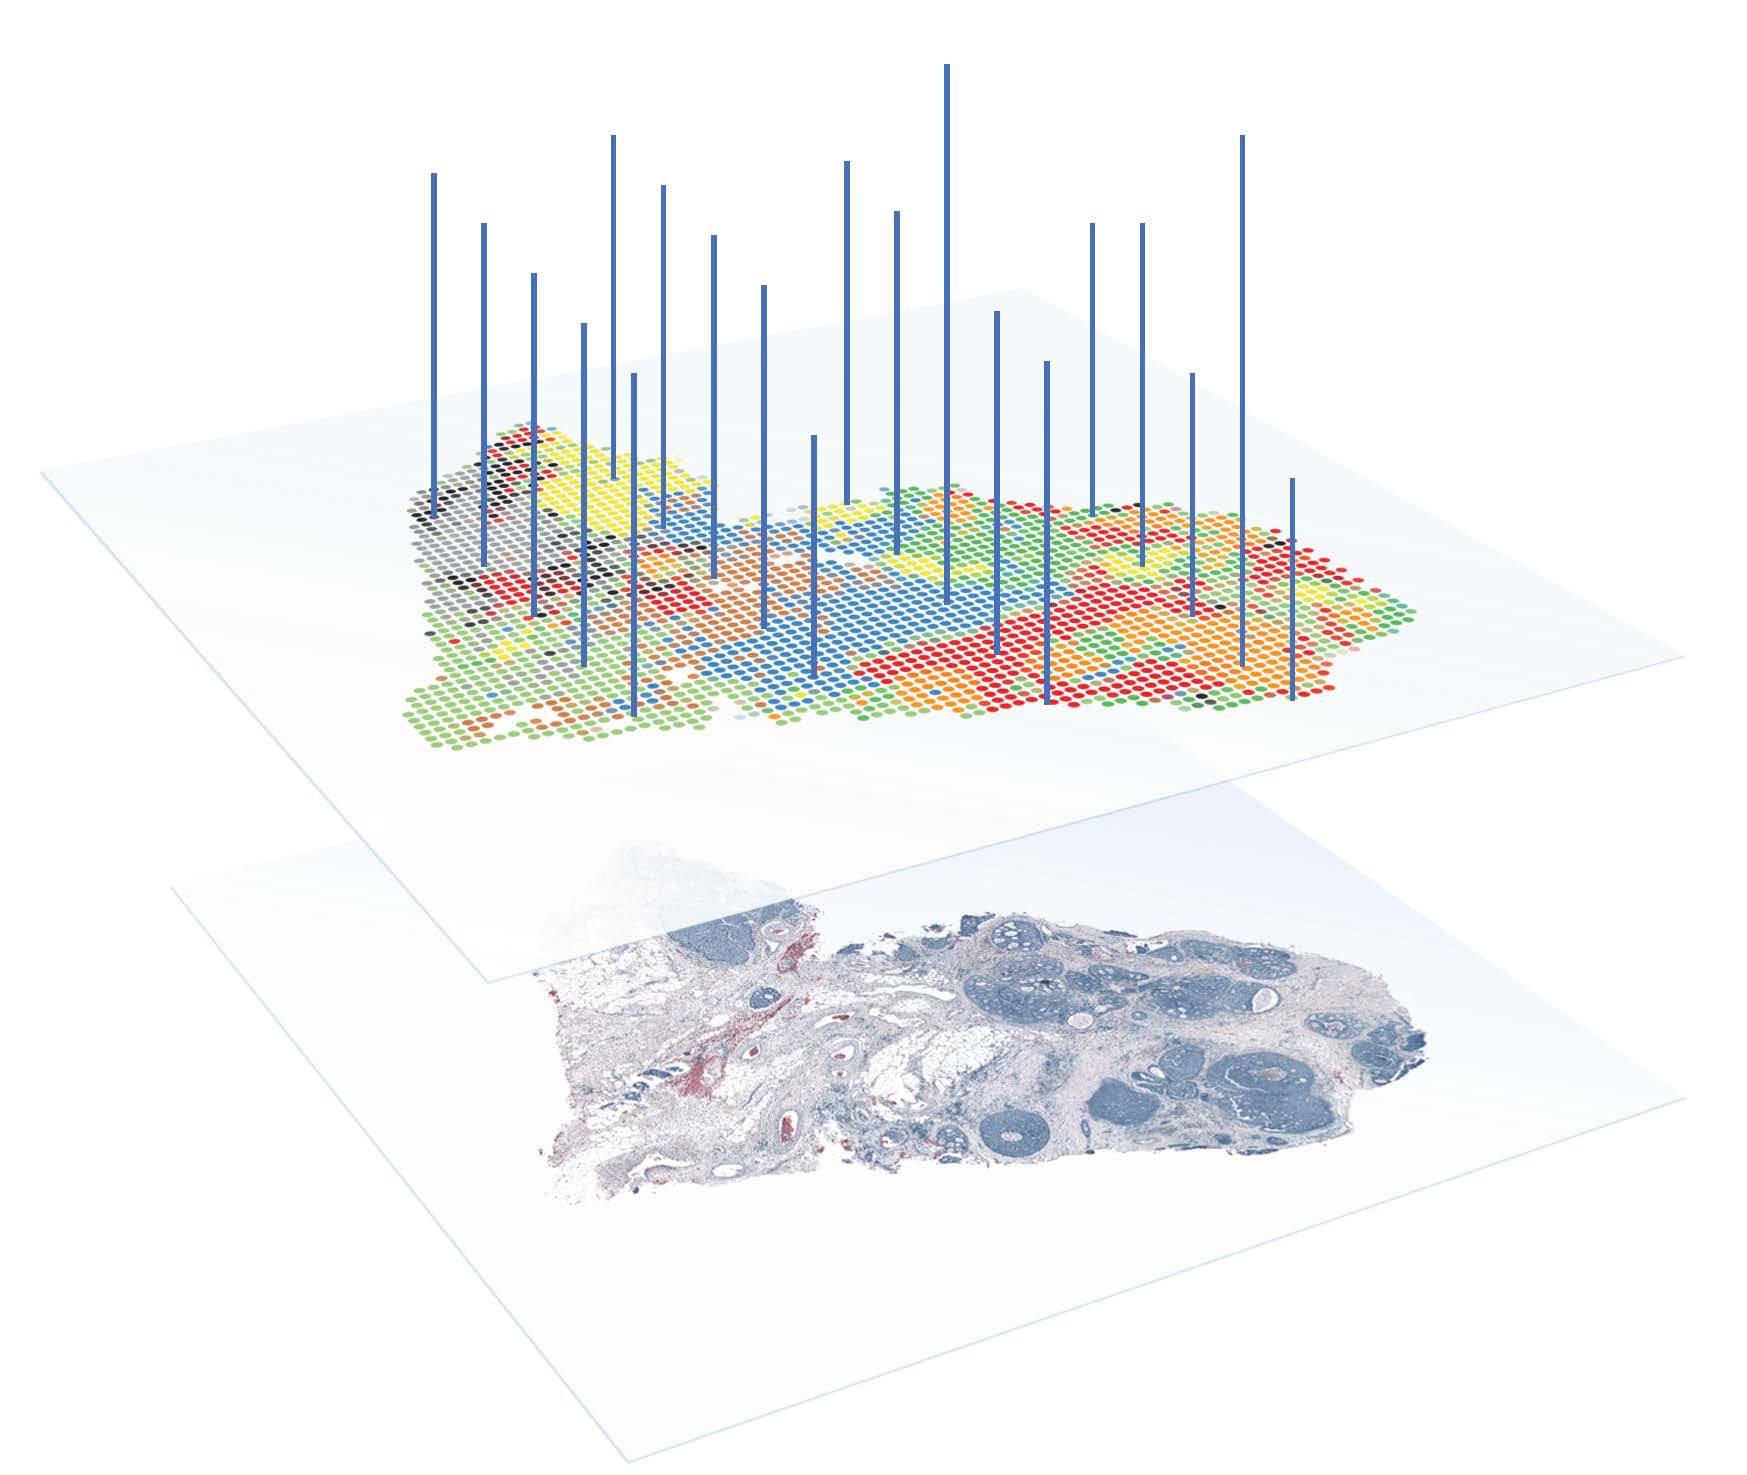
Omics-based drug discovery cannot flourish without a deep understanding of disease mechanisms. Therefore, the second pillar of our research focuses on leveraging emerging single-cell RNA-seq, spatial transcriptomics, rich bulk gene expression profiles, and advanced machine learning to identify novel biomarkers and therapeutic targets. We started this endeavor by working with local physicians to predict which patients with multiple organ dysfunction syndrome (MODS) would need ECMO life support (Shankar, EBioMedicine, 2021). We currently use single-cell omics to delineate cell composition and cell-cell interactions.
In addition to the MODS biomarker work, four projects are underway: 1) characterizing the microenvironment of liver diseases through in silico analysis of bulk tissues and spatial transcriptomics (GitHub), 2) portraying the pan-cancer liver metastasis microenvironment (GitHub), 3) discovering bispecific antibody targets for cancer immunotherapy (GitHub), and 4) predicting the surfaceome using single-cell transcriptomics and transfer learning (GitHub).
Virtual platform to support translational drug discovery
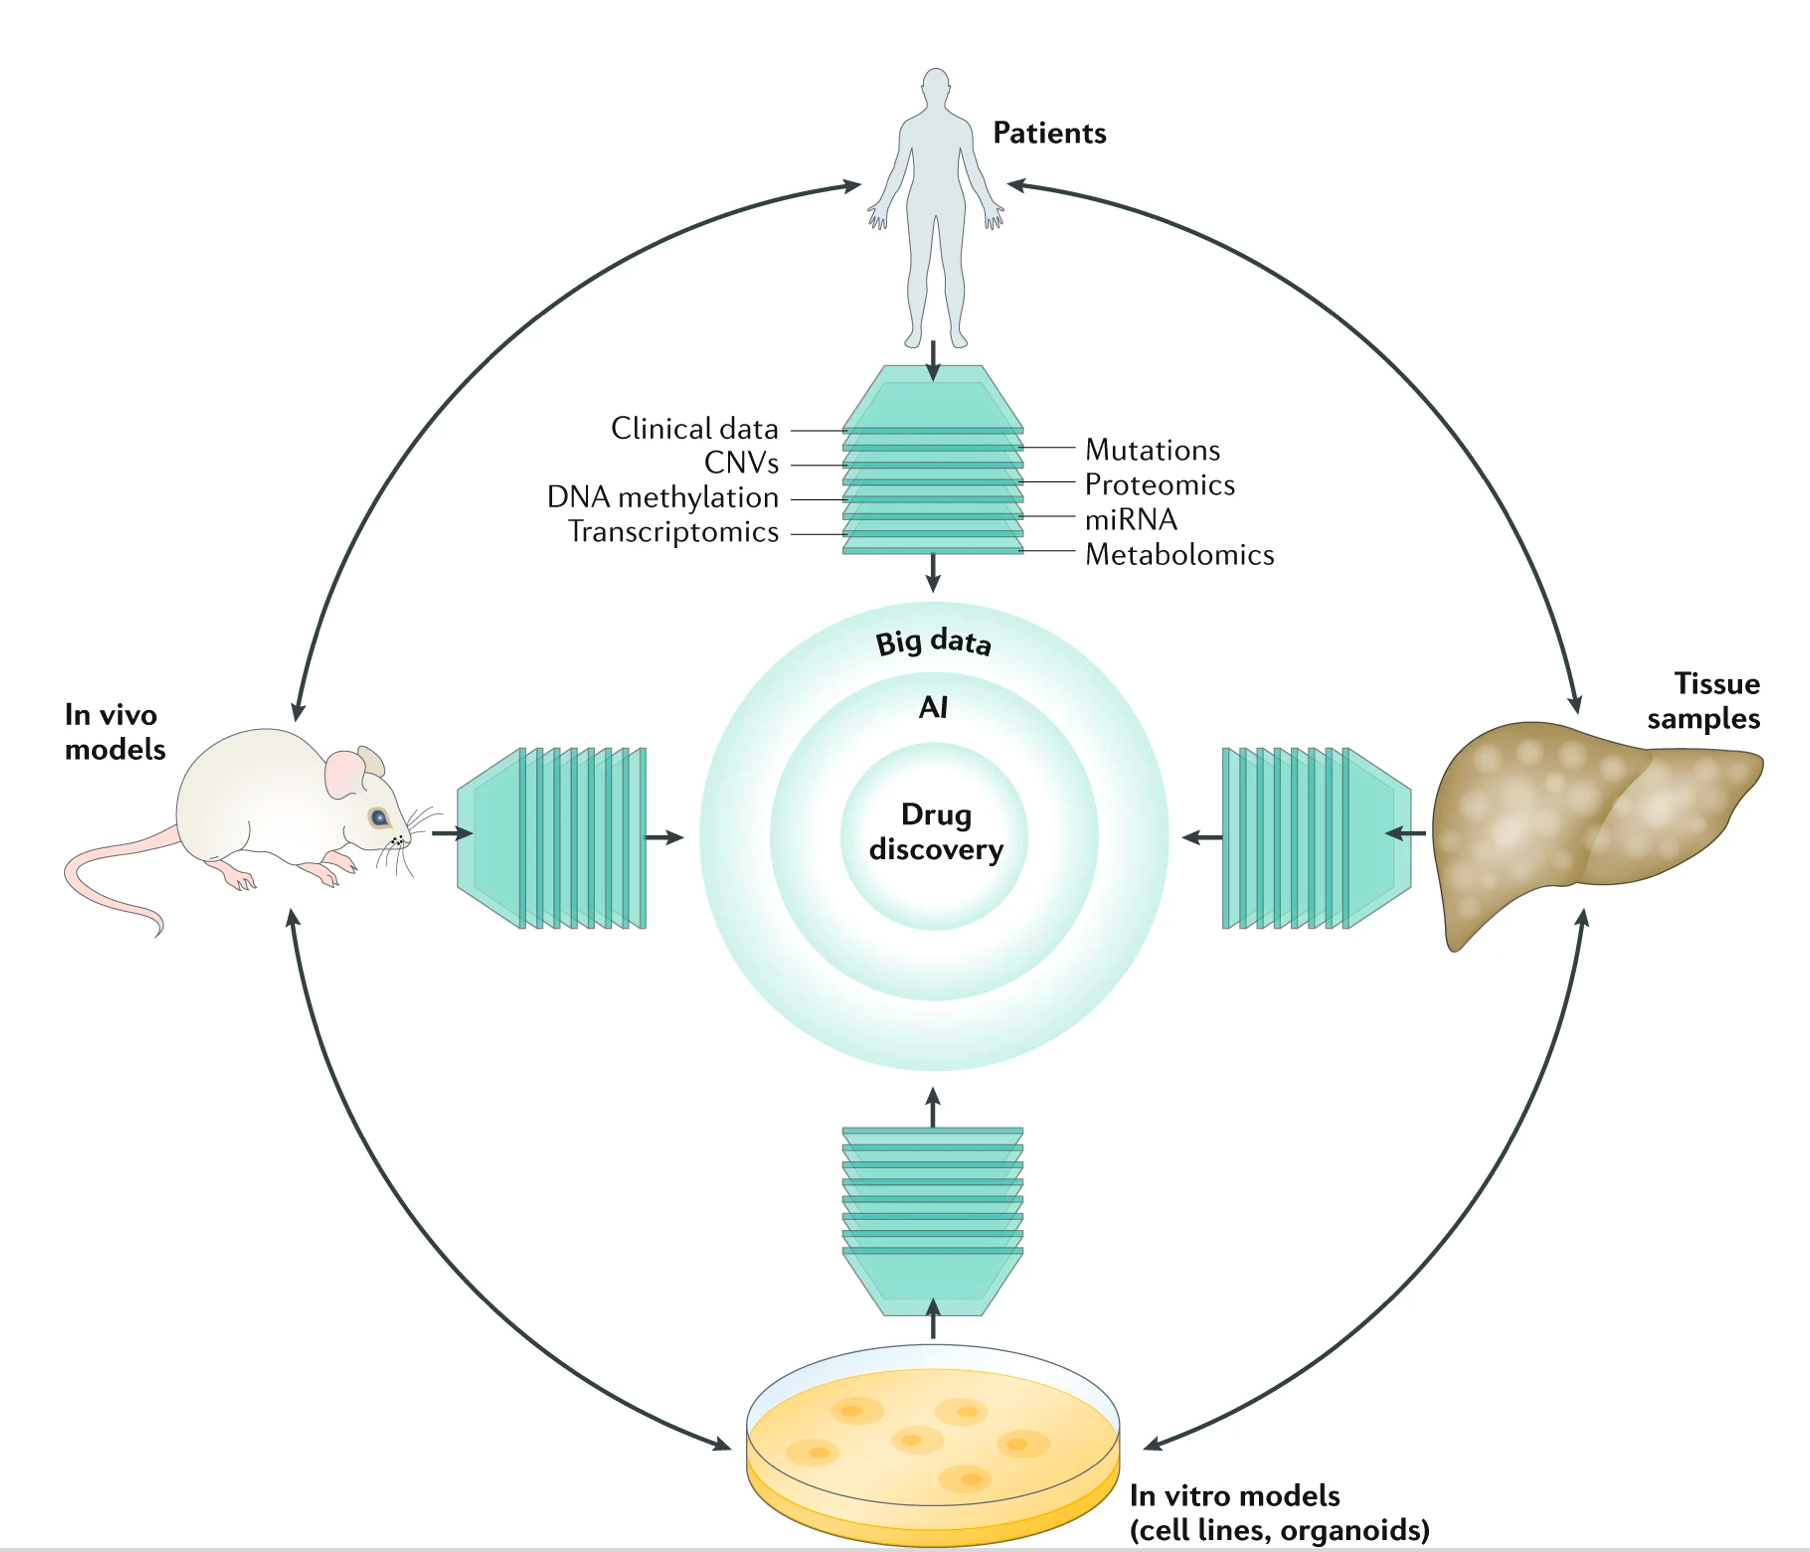
To increase drug discovery success rates, we must scrutinize every step of translational research. The lab is dedicated to developing a virtual platform powered by machine learning and data analytics. The platform includes tumor sample selection, reference normal tissue selection, cell line evaluation, pharmacogenomic data correction, and EHR data cleaning and mining (MetBERT). We recently developed TransCell, which enables in silico characterization of genomic features and cellular responses solely from gene expression data. The lab continues to leverage open data and proprietary data (EHR data from 2 million patients and more than 8,000 biobank patient specimens at Corewell Health) and to develop computational tools that answer important questions in translational research.